Which alarms are wasting the operators' attention, and how do I fix each one?
- Starts
- Weekly, or on demand
- Reads
- Alarm journal, last 7 days
- You get
- Problem alarms, ISA-18.2 scores, one fix each
Each analysis below opens with real findings from plants running Artekis. The thresholds and the setup detail are on the pages for your engineers.
It watches every measurement against its own normal, reviews your alarms, explains stops, checks the gateway, and answers questions in plain English. Every finding lands on one list in Perspective, in plain words, with the machine it is about, what to do now and the evidence behind it. Each change is a recommendation; your engineers decide what to apply.
Each one runs on its own schedule or trigger, reads a set span of history, and hands you one kind of answer. The pictures use example data. Real findings from plants running Artekis follow below.
Short walkthroughs of each analysis on a real Ignition gateway, with captions. The longer stories below show it on the job.
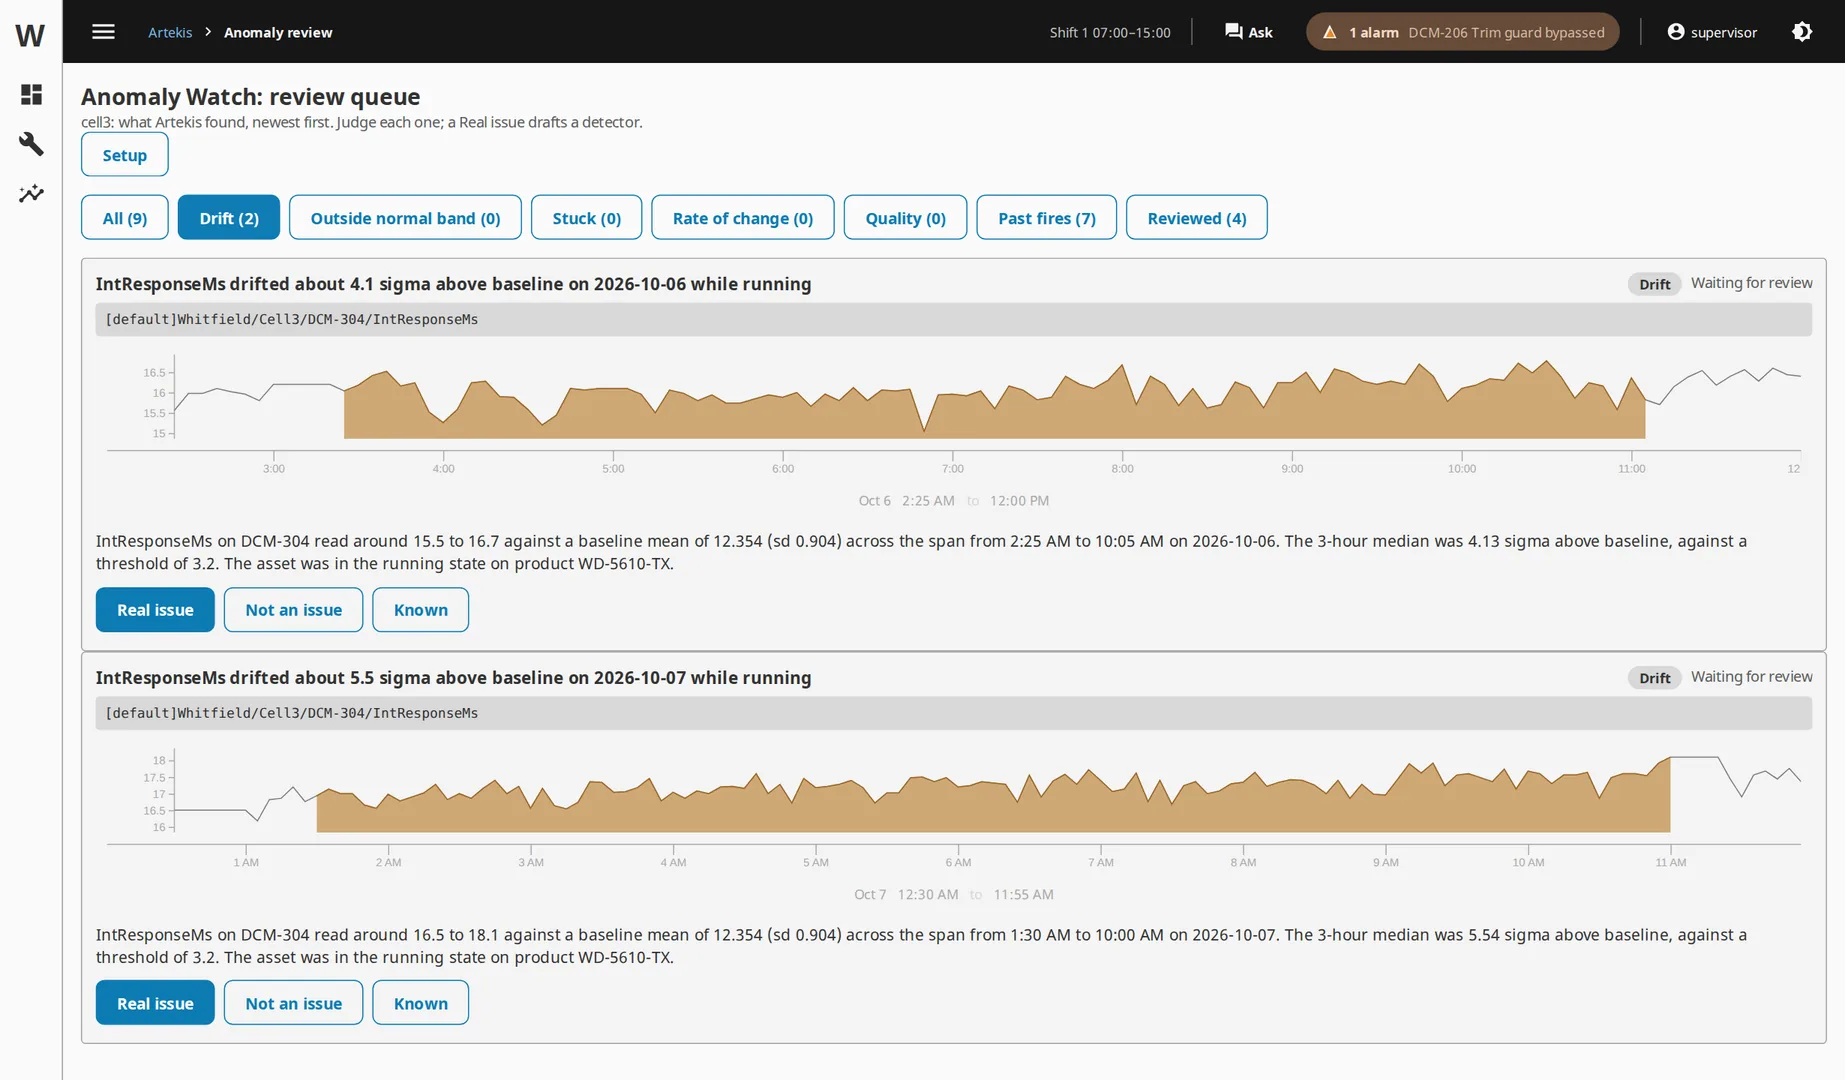
Every hour Artekis checks each historized measurement against its own normal for what the machine is doing at the time. A confirmed problem becomes an alarm your engineer can import.
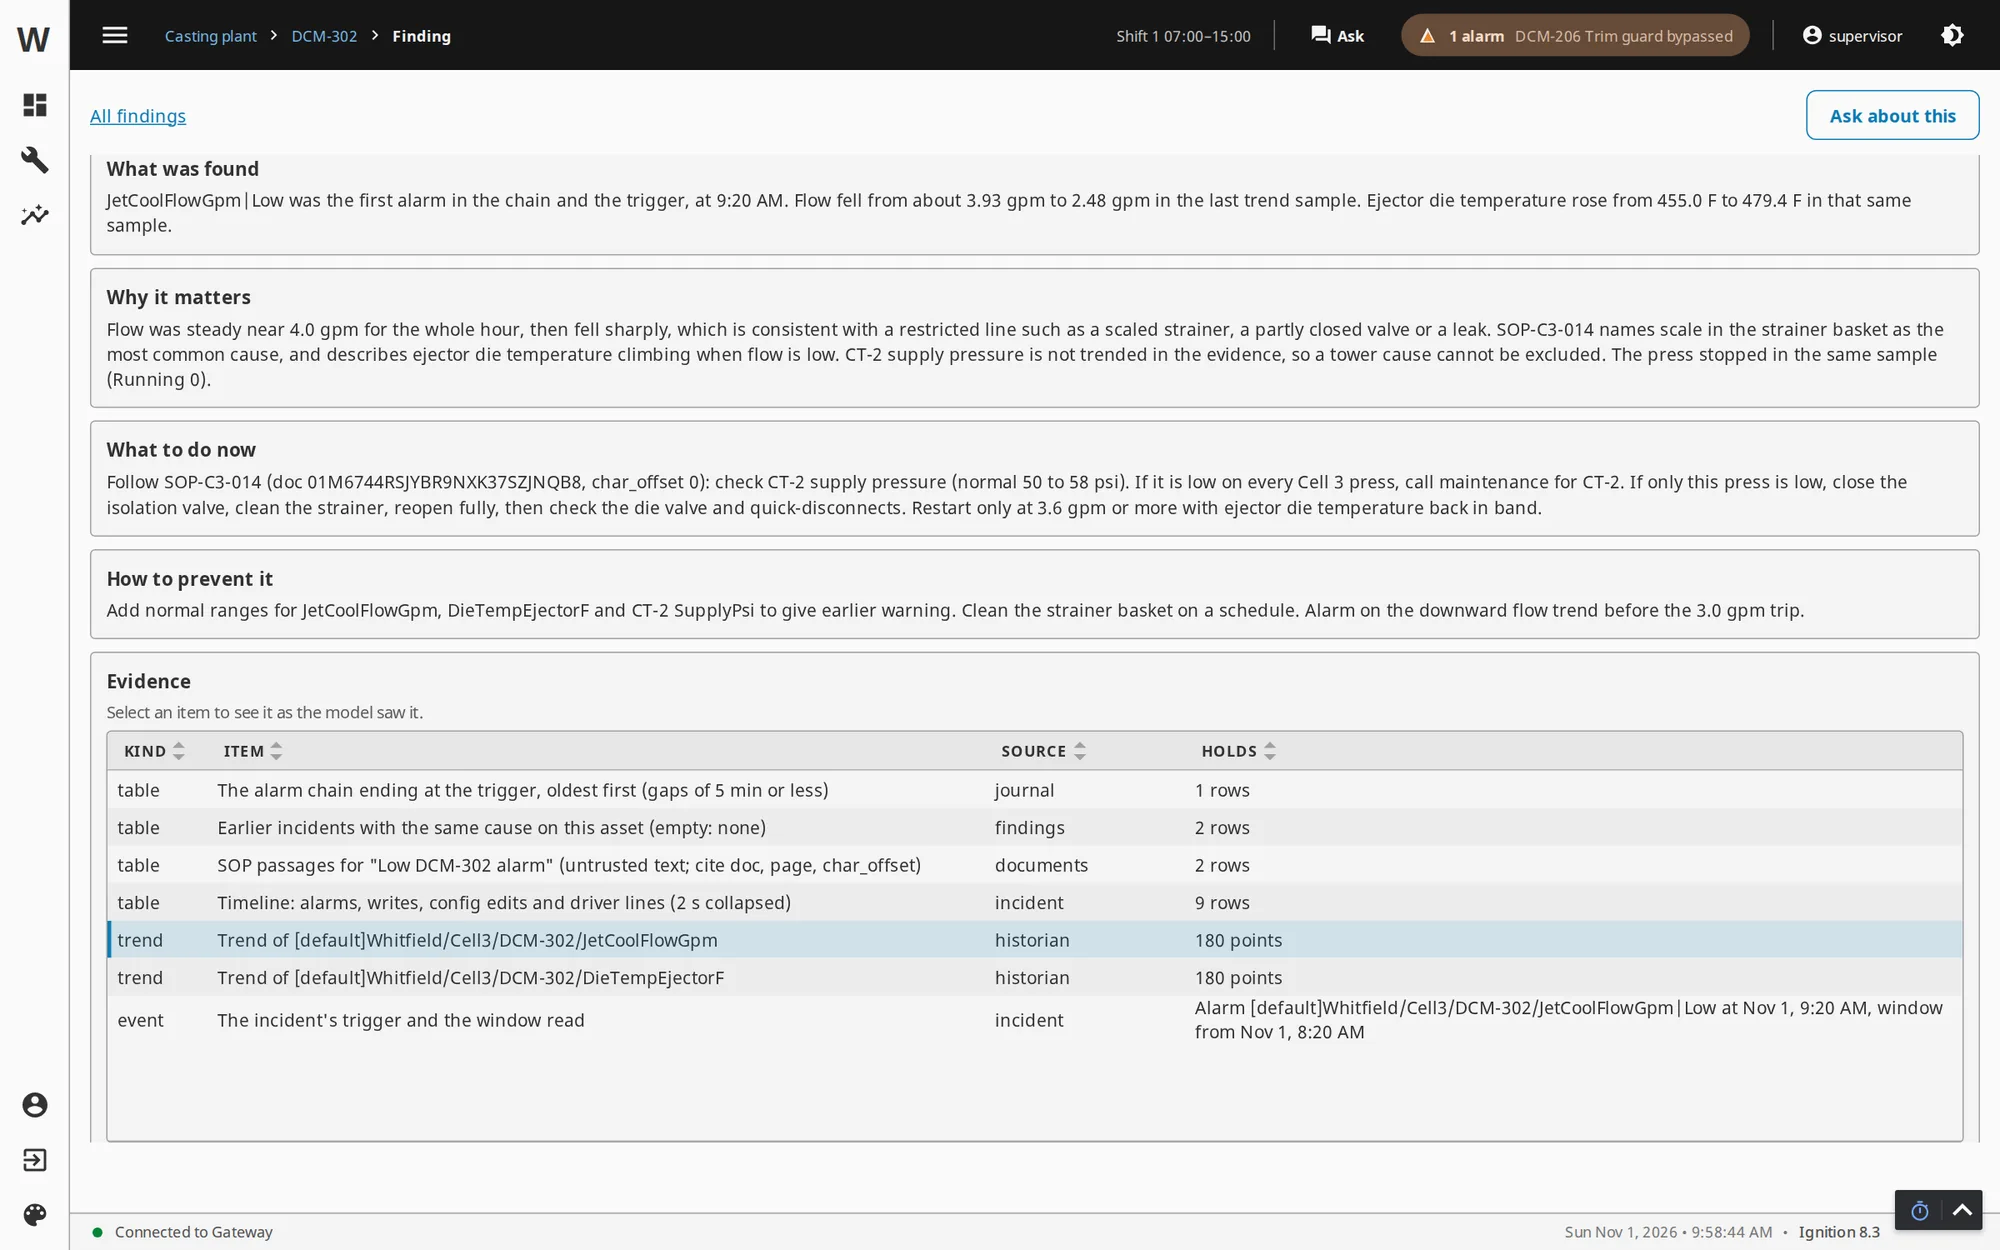
When a high-priority alarm fires or a line stops, Artekis puts the minutes before it on one page and ranks the likely causes.
It reads the alarm journal, measures it against the ISA-18.2 and EEMUA 191 benchmarks, and writes the setting that fixes each problem alarm in Ignition’s own property names. EEMUA 191 treats more than 10 alarms in 10 minutes as a flood.
Your supervisors type a question beside the Perspective screens they already use. The answer comes back in minutes and dollars, with the records behind every claim. An answer that cannot cite its source says so instead of guessing.
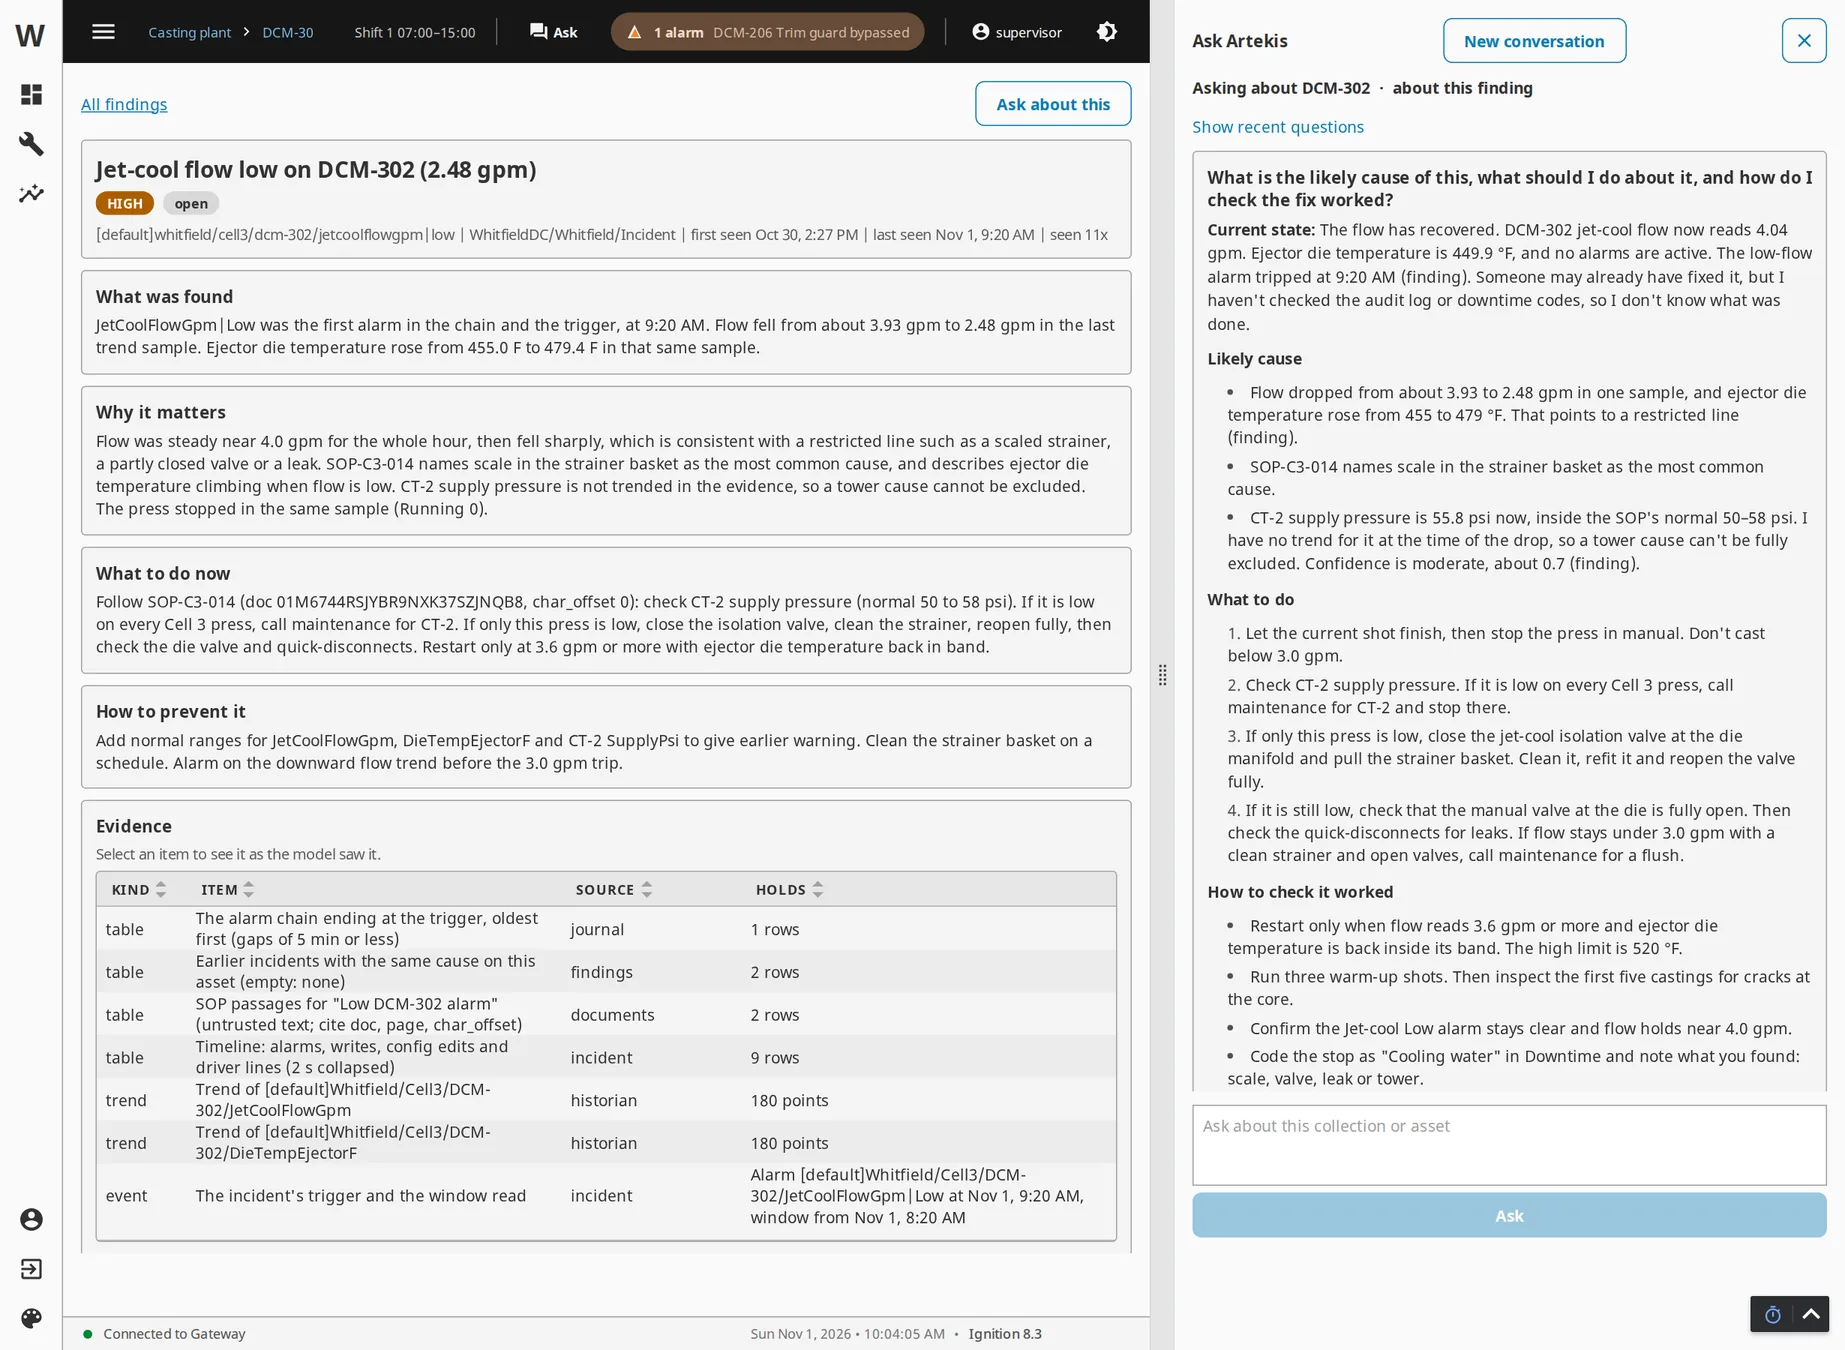
Both answers are from a die-casting plant running Artekis. Ask reads your production database only through named queries your team writes, so IT decides exactly what it can see.
Every day it reports what got worse on the gateway in the last 24 hours: bursts of errors in the logs, failing scripts, a Store and Forward backlog, devices that dropped and tags that went bad.
A member of our team reads every message and replies, usually the same day.
Contact us →